
Databricks Unity Catalogue
Databricks Unity Catalogue - When i execute the code i get this error: I have a separate databricks workspace for each environment, and i am buidling an azure devops pipeline to deploy a databricks asset bundles to these. However, it wasn't clear from. I am trying to connect to databricks using java code. First, install the databricks python sdk and configure authentication per the docs here. In community or free edition you only have access to serverless compute.
I'm trying to connect from a databricks notebook to an azure sql datawarehouse using the pyodbc python library. Here is the code i have so far: When running a databricks notebook as a job, you can specify job or run parameters that can be used within the code of the notebook. It's not possible, databricks just scans entire output for occurences of secret values and replaces them with [redacted]. I have a separate databricks workspace for each environment, and i am buidling an azure devops pipeline to deploy a databricks asset bundles to these.

Databricks Unity Catalog Robust Data Governance & Discovery
When i execute the code i get this error: Dbfs or databricks file system is the legacy way to interact with files in databricks. I'm trying to connect from a databricks notebook to an azure sql datawarehouse using the pyodbc python library. There is a lot of confusion wrt the use of parameters in sql, but i see databricks has.

Unity Catalog Databricks vrogue.co
However, it wasn't clear from. In community or free edition you only have access to serverless compute. I am trying to connect to databricks using java code. There is a lot of confusion wrt the use of parameters in sql, but i see databricks has started harmonizing heavily (for example, 3 months back, identifier () didn't work with. First, install.

Databricks Unity Catalog Everything You Need to Know
When i execute the code i get this error: Dbfs or databricks file system is the legacy way to interact with files in databricks. Databricks is smart and all, but how do you identify the path of your current notebook? I have a separate databricks workspace for each environment, and i am buidling an azure devops pipeline to deploy a.

Databricks Unity Catalog with Zeashan Pappa Software Engineering Daily
When i execute the code i get this error: I am trying to connect to databricks using java code. In community or free edition you only have access to serverless compute. The guide on the website does not help. I'm trying to connect from a databricks notebook to an azure sql datawarehouse using the pyodbc python library.
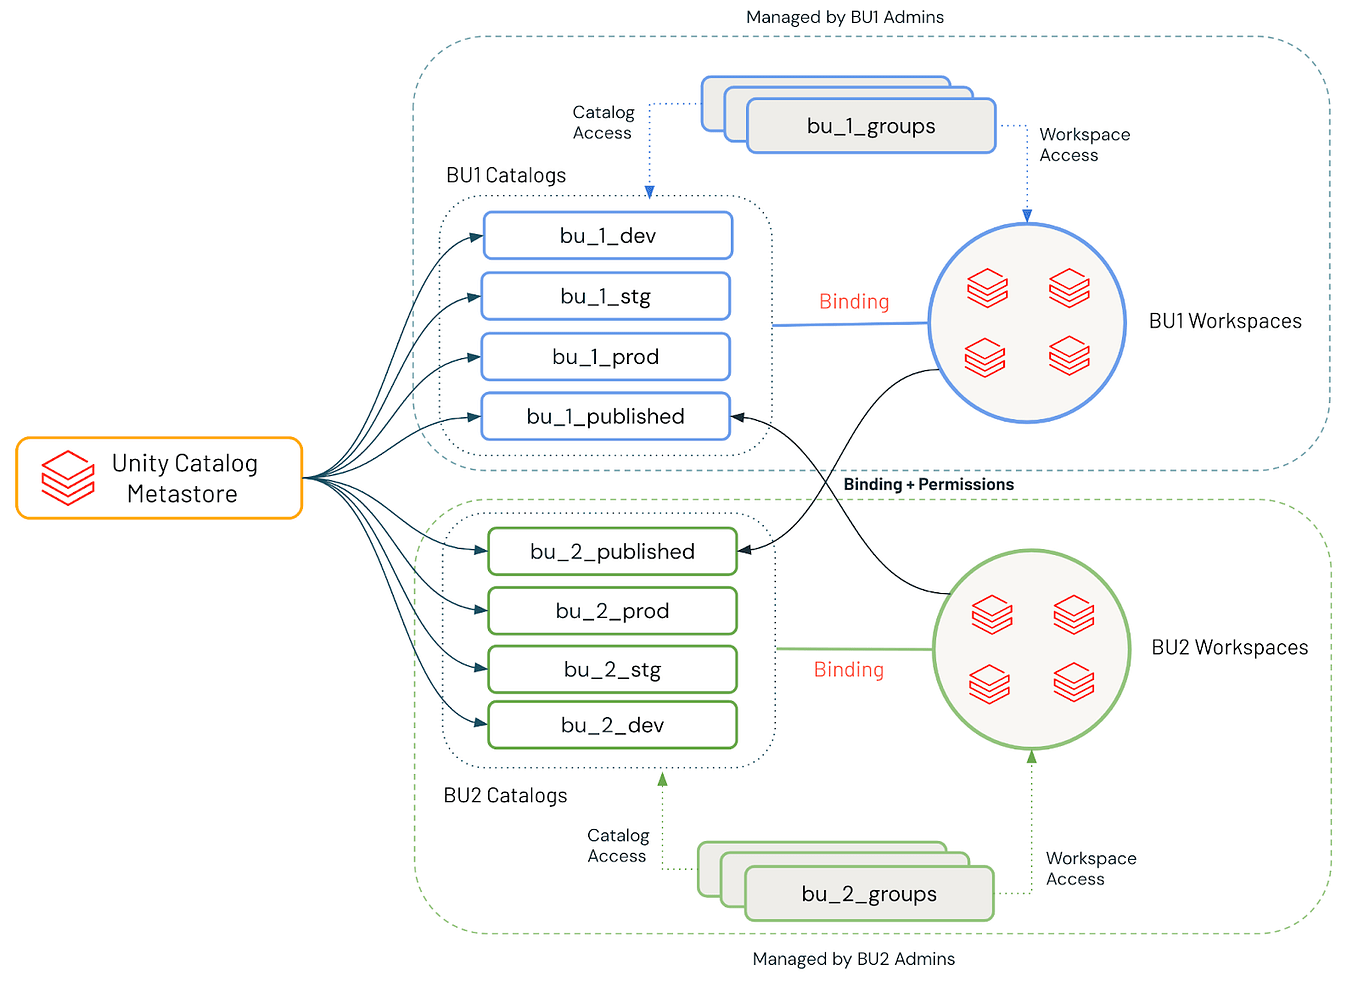
Bidirectional sync between Databricks Unity Catalog and Microsoft
It's not possible, databricks just scans entire output for occurences of secret values and replaces them with [redacted]. I'm trying to connect from a databricks notebook to an azure sql datawarehouse using the pyodbc python library. However, it wasn't clear from. The guide on the website does not help. There is a lot of confusion wrt the use of parameters.
Databricks Unity Catalogue - The guide on the website does not help. I am trying to connect to databricks using java code. I'm setting up a job in the databricks workflow ui and i want to pass parameter value dynamically, like the current date (run_date), each time the job runs. First, install the databricks python sdk and configure authentication per the docs here. When i execute the code i get this error: Databricks is smart and all, but how do you identify the path of your current notebook?
I am trying to connect to databricks using java code. First, install the databricks python sdk and configure authentication per the docs here. I have a separate databricks workspace for each environment, and i am buidling an azure devops pipeline to deploy a databricks asset bundles to these. Dbfs or databricks file system is the legacy way to interact with files in databricks. When running a databricks notebook as a job, you can specify job or run parameters that can be used within the code of the notebook.
The Guide On The Website Does Not Help.
It's not possible, databricks just scans entire output for occurences of secret values and replaces them with [redacted]. When i execute the code i get this error: In community or free edition you only have access to serverless compute. I'm setting up a job in the databricks workflow ui and i want to pass parameter value dynamically, like the current date (run_date), each time the job runs.
I Am Trying To Connect To Databricks Using Java Code.
It is helpless if you transform the value. Databricks is smart and all, but how do you identify the path of your current notebook? I have a separate databricks workspace for each environment, and i am buidling an azure devops pipeline to deploy a databricks asset bundles to these. I'm trying to connect from a databricks notebook to an azure sql datawarehouse using the pyodbc python library.
When Running A Databricks Notebook As A Job, You Can Specify Job Or Run Parameters That Can Be Used Within The Code Of The Notebook.
There is a lot of confusion wrt the use of parameters in sql, but i see databricks has started harmonizing heavily (for example, 3 months back, identifier () didn't work with. First, install the databricks python sdk and configure authentication per the docs here. However, it wasn't clear from. Here is the code i have so far: